Powering Physical AI with Real-World Ego Datasets

Human vs. Model Agreement: Reliable Benchmarks for Embodied AI
Content Menu
● Human Agreement vs. Model Agreement: What Is the Difference?
● Why Inter-Rater Consistency Shapes Benchmark Reliability
>> Agreement Establishes Reproducibility, Not Truth
>> Disagreement Can Reveal Missing Information
● How to Measure Human vs. Model Agreement
>> Percentage Agreement: An Accessible First Check
>> Cohen’s Kappa and Fleiss’ Kappa
>> Temporal and Spatial Agreement
● Can a Model Outperform Human Annotators?
● Three Benchmark Challenges Specific to Embodied AI
>> 1. Temporal Ambiguity Can Masquerade as Model Error
>> 2. Multimodal Synchronization Affects Interpretation
>> 3. Human Demonstrations Are Not Robot Action Labels
● A Practical Workflow for More Reliable Benchmarks
>> Step 1: Define the Evaluation Target
>> Step 2: Run an Independent Annotation Pilot
>> Step 3: Diagnose Disagreement
>> Step 5: Preserve Independent Labels
>> Step 6: Protect the Evaluation Split
>> Step 7: Publish an Interpretable Report
● An Illustrative Example: Better Collection or Better Annotation?
● What Large Robotics Datasets Teach About Coverage
● How Virdyn Can Support Agreement-Aware Data Development
● Build a Benchmark You Can Explain
>> What Is the Main Difference Between Human and Model Agreement?
>> Does High Annotator Agreement Guarantee Accurate Labels?
>> Which Agreement Metric Is Best for Embodied AI?
>> Should Disputed Examples Be Removed?
>> Can Simulated Data Replace Real-World Evaluation?
Human vs. model agreement is not simply a contest between people and algorithms. It is a question of whether an evaluation measures meaningful performance against a trustworthy reference. Human agreement shows how consistently annotators interpret the same evidence. Model agreement shows how closely a system’s predictions match a specified reference. Benchmark reliability depends on understanding both—and recognizing that neither automatically proves correctness.
For embodied AI, this distinction becomes especially important. A robot must interpret changing scenes, understand instructions, and act in the physical world. If annotators disagree about when a grasp begins or whether a task succeeds, an apparently precise model score can hide an unstable evaluation target.
My preferred starting point is therefore straightforward: validate the reference before interpreting the score. This article explains how to compare human and model agreement, select appropriate metrics, and build more useful benchmarks for real-world robotics.
Human Agreement vs. Model Agreement: What Is the Difference?
Human agreement usually means inter-annotator agreement: the consistency of independent judgments about the same examples. Model agreement needs a more explicit definition. It may describe agreement with individual annotators, a majority vote, an adjudicated reference, or other models.
These comparisons answer different questions.
| Dimension | Human agreement | Model agreement |
|---|---|---|
| Main comparison | Annotator against annotator | Prediction against a defined reference |
| Primary purpose | Evaluate annotation reproducibility | Evaluate alignment with the reference |
| Typical evidence | Independent labels or ratings | Predictions and reference labels |
| Common metrics | Percentage agreement, kappa, alpha | Accuracy, F1, agreement coefficients |
| Main limitation | Consistent annotators can share errors | Strong alignment can reproduce reference errors |
| Robotics example | Agreement on grasp boundaries | Matching approved grasp labels |
Consider a warehouse video. One annotator labels “grasp” when fingers contact a carton. Another waits until the carton leaves the shelf. Their disagreement may reflect different definitions rather than careless work.
A model trained on either convention could perform consistently while receiving different benchmark scores. The first problem to solve is the task definition—not necessarily the model.
Why Inter-Rater Consistency Shapes Benchmark Reliability
Agreement Establishes Reproducibility, Not Truth
High inter-rater agreement suggests that people can apply an annotation scheme consistently. That makes the resulting labels easier to reproduce and interpret.
However, reliability and validity are different. Reliability concerns consistency; validity concerns whether an evaluation measures what it claims to measure.
Annotators might consistently label “successful placement” whenever an object reaches a target area. If the task also requires stability and correct orientation, the labels remain consistent but incomplete.
For robotics, benchmark validity therefore requires operational definitions that reflect the intended physical outcome.
Disagreement Can Reveal Missing Information
Not every disagreement is annotation noise.
Some examples are ambiguous because the camera cannot show the relevant event. Others allow several reasonable interpretations. In subjective tasks, differences may reflect meaningful variation in human judgment.
Useful disagreement categories include:
-
Unclear instructions.
-
Missing visual evidence.
-
Different temporal boundaries.
-
Insufficient domain knowledge.
-
Multiple acceptable interpretations.
-
Accidental labeling errors.
Each category calls for a different response. Retraining annotators will not reveal a contact event hidden behind a hand. Likewise, improved camera coverage will not resolve an undefined success criterion.
How to Measure Human vs. Model Agreement
Percentage Agreement: An Accessible First Check
Percentage agreement reports how often judgments match. It is easy to explain and useful for initial quality monitoring.
Its limitation is class imbalance. If most clips show successful actions, annotators can agree frequently by choosing “success,” while remaining inconsistent on rare failures.
Always inspect agreement by category rather than relying only on the overall percentage.
Cohen’s Kappa and Fleiss’ Kappa
Cohen’s kappa measures chance-adjusted agreement between two raters assigning categorical labels.
Fleiss’ kappa supports multiple ratings per item under its relevant sampling assumptions. It is commonly used for multi-rater categorical annotation.
Both require careful interpretation. Label prevalence and differences in annotators’ category usage can affect the results. A kappa score should therefore accompany label distributions and a confusion analysis.
Krippendorff’s Alpha
Krippendorff’s alpha accommodates multiple annotators, missing annotations, and different measurement scales when the disagreement function is chosen appropriately.
It is useful when annotation coverage is incomplete or when labels are ordinal rather than purely categorical.
However, no single coefficient determines whether a robotics benchmark is ready for deployment. Acceptance criteria should reflect the task, uncertainty, and consequences of error.
Temporal and Spatial Agreement
Embodied AI annotations often describe intervals, trajectories, or geometry rather than isolated categories.
Additional measures may include:
-
Temporal intersection over union for action segments.
-
Start- and end-boundary deviation.
-
Spatial overlap for segmentation.
-
Position and orientation errors for pose estimates.
-
Precision and recall for safety-relevant events.
Correlation alone is insufficient for exact agreement. Two raters can produce strongly correlated numerical estimates while one consistently records higher values.
Can a Model Outperform Human Annotators?
Yes—but the claim needs a clearly defined comparison.
A model may match an adjudicated reference more often than an individual annotator. That does not establish superiority across the entire task, nor does it prove that the reference captures physical reality perfectly.
Similarly, human–human agreement is not a universal mathematical ceiling on model accuracy. The result depends on the raters, aggregation method, available evidence, and evaluation target.
A credible comparison should specify:
-
Whether humans and models receive equivalent information.
-
Whether reference construction excludes the evaluated annotator.
-
How ambiguous examples are scored.
-
Whether model development used related evaluation data.
-
Whether improvements persist across important task subsets.
For embodied AI, there is another essential distinction: recognizing an action in video is not the same as executing that action successfully.
Three Benchmark Challenges Specific to Embodied AI
1. Temporal Ambiguity Can Masquerade as Model Error
Imagine a person transferring a container from a shelf to a table.
Possible transition points include initial contact, secure grip, lift-off, arrival, and release. Without a shared labeling convention, several timestamps may be defensible.
A useful protocol defines observable anchors and handles uncertainty explicitly. For example, “lift begins” could mean the first visible separation between the container and its support surface.
Where the evidence remains unclear, annotators should record uncertainty rather than invent precision.
2. Multimodal Synchronization Affects Interpretation
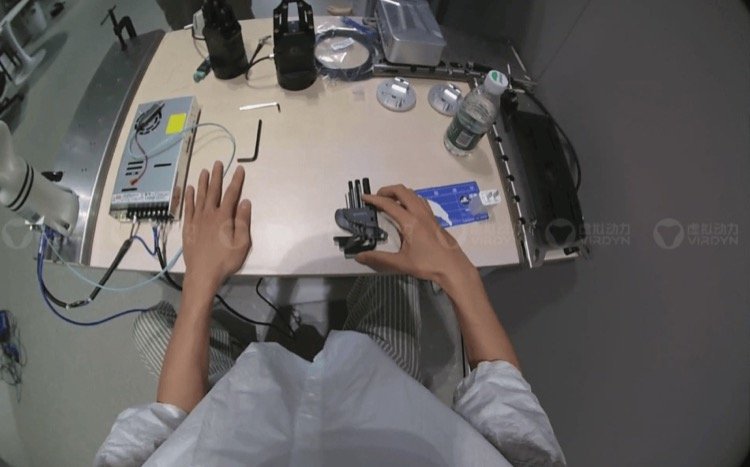
Egocentric datasets may combine stereo RGB video, IMU measurements, camera pose, and derived hand or body motion.
These streams need compatible timing and documented coordinate conventions. Misalignment can make a motion signal appear to precede or follow the corresponding visual event.
Before attributing disagreement to annotators, inspect:
-
Timestamp consistency.
-
Missing or duplicated frames.
-
Calibration records.
-
Sensor alignment.
-
Coordinate-system definitions.
Annotations can be internally consistent and still become misleading when attached to the wrong moment or reference frame.
3. Human Demonstrations Are Not Robot Action Labels
First-person human demonstrations provide valuable evidence about task order, hand–object interaction, and environmental context.
However, they do not automatically provide robot joint commands, calibrated end-effector trajectories, or force measurements.
For vision-language-action model development, teams should distinguish directly recorded signals from estimated representations and robot-specific supervision.
This distinction also matters when comparing real and simulated data. Shared labels do not guarantee equivalent visibility, contact dynamics, or physical behavior.
A Practical Workflow for More Reliable Benchmarks
Step 1: Define the Evaluation Target
Specify whether the benchmark evaluates perception, action recognition, instruction understanding, task completion, or physical execution.
Write an operational success definition before collection begins. “Place the object correctly” is insufficient without location, orientation, stability, and timing requirements.
Step 2: Run an Independent Annotation Pilot
Select a pilot containing routine examples, failures, occlusions, and difficult transitions.
Have multiple annotators label it independently before discussion. This establishes a baseline without agreement being artificially increased through collaboration.
Step 3: Diagnose Disagreement
Review disagreements by cause, not just frequency.
Separate unclear policies from missing evidence and genuine interpretive variation. Maintain a decision log explaining guideline changes and their rationale.
Step 4: Revise and Recheck
Add examples and counterexamples to the guidelines. Then test the revised protocol on fresh material.
Repeatedly reviewing the same examples can improve apparent agreement without demonstrating that the instructions generalize.
Step 5: Preserve Independent Labels
Keep original judgments alongside adjudicated labels.
This supports audits, allows alternative aggregation methods, and preserves uncertainty that a single final label would otherwise conceal.
Step 6: Protect the Evaluation Split
Separate related recordings at the task, session, participant, environment, or object level as appropriate.
Adjacent clips from the same recording can share substantial visual information. Treating them as independent train and test examples risks overstating generalization.
Step 7: Publish an Interpretable Report
Report human agreement, model results, label distributions, uncertainty, and performance on important subsets.
Where observations are grouped within sessions or environments, uncertainty estimates should respect that grouping rather than treating every video frame as independent.
An Illustrative Example: Better Collection or Better Annotation?
Suppose a pilot contains 200 first-person clips of workers picking and placing small components. Two annotators disagree on 40 clips.
These figures are hypothetical, not Virdyn performance results.
Inspection reveals three causes:
| Cause | Appropriate intervention |
|---|---|
| Inconsistent grasp definitions | Revise event boundaries and examples |
| Occluded release events | Improve collection viewpoints or mark uncertainty |
| Unclear placement requirements | Define acceptable orientation and stability |
The practical lesson is that disagreement can guide investment.
More annotation review may help when instructions are inconsistent. It cannot fully compensate for footage that never records the decisive evidence. In that situation, collection design deserves attention before labeling volume increases.
What Large Robotics Datasets Teach About Coverage
The DROID project reports 76,000 demonstration trajectories, approximately 350 hours of interaction data, 564 scenes, and 86 tasks.
Its relevance here is diversity: robotics datasets must account for variation across environments and interactions, not merely accumulate additional frames.
These collection figures do not establish annotation reliability by themselves. A large dataset still needs clear task definitions, appropriate evaluation splits, and documented quality controls.
Dataset scale and benchmark trustworthiness are complementary—not interchangeable.
How Virdyn Can Support Agreement-Aware Data Development
Based on the supplied company information, Virdyn combines egocentric collection, multimodal dataset development, annotation, quality inspection, and simulation capabilities.
That combination can support a workflow in which collection requirements and labeling rules are designed together.
For a VDEgo-C2-based project, buyers should request a documented specification covering:
-
Captured modalities and timestamp conventions.
-
Calibration and synchronization checks.
-
Annotation definitions and uncertainty handling.
-
Quality-control sampling and acceptance criteria.
-
Data provenance and participant permissions.
-
Delivery schemas and version history.
File formats such as MP4, CSV, JSON, and PLY support different data types, but formats alone do not establish training readiness.
The more useful deliverable is a documented relationship between recordings, derived signals, labels, and evaluation rules.
Build a Benchmark You Can Explain
Before expanding data collection, establish what success means, how independently people recognize it, and how uncertainty reaches the final evaluation.
For an embodied AI project, bring Virdyn a representative task list, intended model use, required modalities, and acceptance criteria. Request a pilot that tests collection visibility, annotation agreement, and delivery usability before committing to larger-scale production.
Frequently Asked Questions
What Is the Main Difference Between Human and Model Agreement?
Human agreement measures consistency among annotators. Model agreement measures alignment between predictions and a specified reference. Neither, by itself, proves correctness.
Does High Annotator Agreement Guarantee Accurate Labels?
No. Annotators can consistently follow an incomplete or mistaken definition. Independent validation and meaningful success criteria remain necessary.
Which Agreement Metric Is Best for Embodied AI?
The appropriate metric depends on the annotation. Categorical labels may use kappa or alpha; action intervals and pose estimates require temporal or spatial measures.
Should Disputed Examples Be Removed?
Not automatically. They may reveal missing evidence, unclear instructions, or important edge cases. Investigate the cause before excluding or retaining them.
Can Simulated Data Replace Real-World Evaluation?
Not by default. Simulation can expand controlled coverage, but real-world evaluation remains necessary to assess relevant differences in appearance, sensing, interaction, and physics.
References
-
iMerit. “Human vs. Model Agreement: How Inter-Rater Consistency Shapes Benchmark Reliability.” Background on annotation consistency, benchmark interpretation, and quality-control workflows. https://imerit.ai/resources/blog/human-vs-model-agreement-how-inter-rater-consistency-shapes-benchmark-reliability/
-
Artstein, R., and Poesio, M. “Inter-Coder Agreement for Computational Linguistics.” Computational Linguistics, 34(4), 555–596, 2008. Methodological foundation for agreement measures and their interpretation. https://aclanthology.org/J08-4004/
-
Krippendorff, K. “Computing Krippendorff’s Alpha-Reliability.” University of Pennsylvania. Technical explanation of alpha and observed versus expected disagreement. https://www.asc.upenn.edu/sites/default/files/2021-03/Computing%20Krippendorff's%20Alpha-Reliability.pdf
-
DROID project. “DROID: A Large-Scale In-the-Wild Robot Manipulation Dataset.” Primary source for the reported trajectories, interaction hours, scenes, and tasks. https://droid-dataset.github.io/
Hot Tags: Embodied AI, AI Data Collection, AI Data Annotation, AI Training Data, Robotics Training Data, Multimodal Datasets, Egocentric Data Collection, Custom AI Datasets, AI Model Evaluation, Inter-Annotator Agreement
SHARE



