Powering Physical AI with Real-World Ego Datasets


Skeleton Annotation for Embodied AI and Robot Training
Content Menu
● What Is Skeleton Annotation in Computer Vision?
>> Skeleton Annotation vs. Other Labeling Methods
● Why Egocentric Skeleton Annotation Matters for Embodied AI
>> Pose Labels Are Not Robot Action Commands
● Design the Skeleton Schema Before Collecting Data
>> Select Keypoints That Match the Task
>> Separate Visibility, Confidence, and Provenance
● Build an Egocentric Data Collection Workflow Around the Labels
>> Check Camera Coverage and Calibration
>> Validate Synchronization, Not Just File Availability
● A Six-Step Skeleton Annotation Workflow
>> 1. Translate the Task Into Observable Events
>> 2. Configure Templates and Point-Level Attributes
>> 3. Label a Representative Pilot
>> 4. Use Automated Suggestions With Human Review
>> 5. Review Sequences, Not Only Individual Frames
>> 6. Validate the Export in the Training Pipeline
● Define Quality Metrics Before Production
● Add Object and Task Context to Hand Keypoints
>> Illustrative Workflow: Warehouse Picking
● Combine Real and Simulated Data Without Hiding the Differences
● How Virdyn Supports Training-Ready Data Production
>> Start With a Pilot Specification
>> What is a skeleton annotation tool?
>> How many keypoints should a hand dataset include?
>> Can 2D skeleton annotation provide 3D ground truth?
>> How should annotators handle hidden finger joints?
>> Are hand keypoints sufficient for robot training?
>> What should a dataset delivery include besides videos?
A skeleton annotation tool connects visual keypoints into meaningful structures, helping computer vision models learn how hands, bodies, and articulated objects move. For embodied AI, however, placing points is only the beginning. Useful training data also needs reliable capture, consistent labels, synchronized measurements, and a clear relationship between human actions and physical tasks.
Consider a person picking a component from a bin and inserting it into a fixture. A bounding box identifies the hand. Skeleton annotation describes its configuration. Task labels explain the action. Together, these layers provide a more useful record of the interaction.
This guide explains how to design that workflow—and where Virdyn’s egocentric data collection and multimodal data services can support it.
What Is Skeleton Annotation in Computer Vision?
Skeleton annotation represents a subject as named keypoints connected by predefined edges. For a human arm, those points might include the shoulder, elbow, and wrist. For a hand, they describe the wrist and finger joints.
The connections establish a consistent structure across images or video frames. Individual points can also carry attributes, such as visibility or annotation status.
Unlike an isolated coordinate, a structured keypoint has an identity and a relationship to neighboring points. That distinction matters when models must recognize posture, estimate movement, or interpret manipulation.
Skeleton Annotation vs. Other Labeling Methods
| Annotation method | What it describes | Typical application |
|---|---|---|
| Bounding boxes | Approximate object location | Hand or object detection |
| Segmentation masks | Visible object boundaries | Shape and contact-region analysis |
| Skeleton annotation | Landmarks and structural relationships | Hand and body pose estimation |
| Temporal action labels | Events across a time interval | Task understanding and sequencing |
These methods complement one another. A robot-learning dataset may need all four rather than a single labeling format.
Why Egocentric Skeleton Annotation Matters for Embodied AI
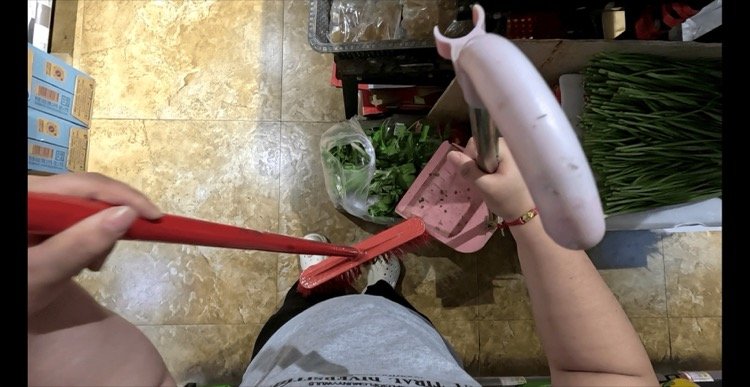
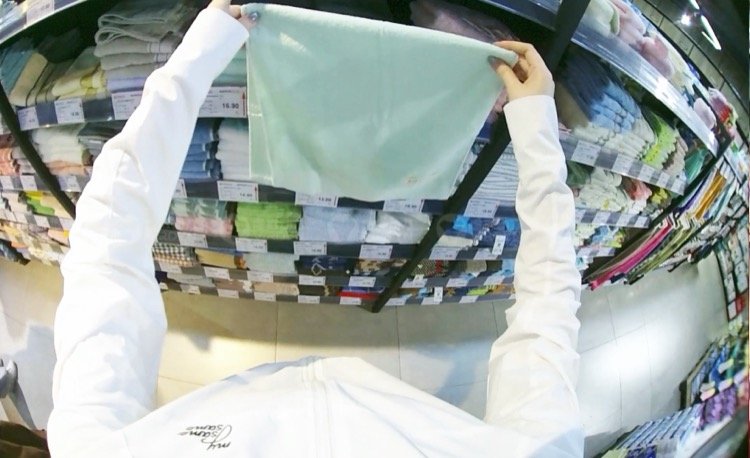
Egocentric video records activity from the participant’s perspective. It brings the camera close to the hands, tools, and objects involved in a task.
This viewpoint is useful for studying manipulation, but it also introduces difficult annotation conditions:
-
Fingers disappear behind objects.
-
Hands leave and re-enter the frame.
-
Head movement changes the viewpoint.
-
Motion blur obscures small joints.
-
Similar-looking actions produce different outcomes.
A useful dataset must represent these difficulties rather than silently remove them.
Ego-Exo4D illustrates the value of combining perspectives and annotation layers. Its resources include synchronized first-person and third-person video, hand and body pose, object masks, and time-indexed descriptions of activity.
The practical lesson is straightforward: keypoints become more informative when connected to task context.
Pose Labels Are Not Robot Action Commands
Human hand trajectories can support representation learning, pose estimation, and activity understanding. They do not automatically provide executable robot commands.
A robot has different joints, reach limits, grippers, and control interfaces. Transferring human demonstrations may require retargeting, additional robot demonstrations, or a separate action-learning process.
For Vision-Language-Action models, define whether the dataset supplies visual observations, language instructions, action targets, or only part of that combination.
Design the Skeleton Schema Before Collecting Data
My recommended starting point is the learning objective—not the annotation interface.
Ask what the model must distinguish. Is the task recognizing a grasp, estimating finger configuration, tracking a worker’s posture, or identifying a failed insertion?
That answer determines which landmarks and supporting labels are necessary.
Select Keypoints That Match the Task
A common hand representation uses 21 landmarks per hand. Ego-Exo4D’s hand annotations follow this arrangement, giving 42 landmarks across both hands.
That convention is useful for compatibility, but it is not a universal requirement. Full-body ergonomics, articulated equipment, and fine manipulation need different structures.
Before production, document:
-
Keypoint names and ordering.
-
Connections between points.
-
Left-hand and right-hand conventions.
-
Image-coordinate definitions.
-
Visibility and uncertainty rules.
-
Required object and task labels.
Freeze a versioned schema after the pilot. Uncontrolled changes can make otherwise valid annotation batches incompatible.
Separate Visibility, Confidence, and Provenance
These fields answer different questions:
-
Visibility: Can the landmark be seen?
-
Confidence: How certain is its location?
-
Provenance: Was it manually labeled or automatically generated?
Do not combine them into one ambiguous score.
A visible joint may still be difficult to locate because of blur. An occluded joint may have an estimated position, but that estimate should not appear identical to a directly observed label.
Build an Egocentric Data Collection Workflow Around the Labels
Annotation quality starts before an annotator opens a frame. Missing visual evidence cannot reliably be repaired by adding more labeling effort.
For first-person hand-pose datasets, collection planning should address camera placement, working distance, lighting, task coverage, and recording continuity.
Check Camera Coverage and Calibration
Run representative tasks before full collection. Verify that the hands and relevant objects remain visible during critical moments—not just while the participant stands still.
Stereo RGB capture can support spatial workflows, but two camera streams alone do not establish reliable 3D ground truth. The pipeline also needs appropriate calibration, synchronized frames, sufficient shared visibility, and reconstruction validation.
Keep camera parameters and coordinate conventions with the delivered data.
Validate Synchronization, Not Just File Availability
RGB video, IMU measurements, and camera-pose information are useful only when their relationships are understood.
Record timestamp units, clock references, sampling rates, dropped-frame events, and any alignment procedure. A matching filename is not evidence of synchronization.
For Virdyn projects using the VDEgo-C2, the supplied product brief describes binocular RGB capture, synchronized IMU data, timestamp recording, camera-pose tracking, local storage, and wireless control. Project-specific performance and available outputs should be confirmed during technical scoping.
A Six-Step Skeleton Annotation Workflow
A strong workflow combines efficient labeling with explicit decision rules.
1. Translate the Task Into Observable Events
Break the activity into meaningful stages.
For a pick-and-place sequence, these might include reaching, grasping, lifting, transporting, and releasing. Define the visible evidence that marks each transition.
Avoid instructions such as “label the action accurately” without explaining what counts as its beginning and end.
2. Configure Templates and Point-Level Attributes
Create the skeleton once and reuse it consistently.
Tools such as Ango Hub support predefined skeleton structures and point-level attributes. These features help teams capture more than coordinates, including whether individual landmarks are visible or occluded.
Test the export before scaling. Information available in the interface must also survive delivery.
3. Label a Representative Pilot
Include difficult examples early:
-
Crossed hands.
-
Small or reflective objects.
-
Fast manipulation.
-
Partial hand visibility.
-
Failed attempts.
-
Changes in lighting or background.
Use the pilot to expose unclear guidelines and estimate review effort. A clean, repetitive clip is not a sufficient production test.
4. Use Automated Suggestions With Human Review
Pre-annotation can reduce repetitive placement work, but predictions require verification.
Check left–right identity, fingertip location, occlusion states, and transitions between frames. Do not assume that smooth-looking motion is correct.
Keep automated and human-reviewed labels distinguishable in the dataset’s provenance records.
5. Review Sequences, Not Only Individual Frames
A frame can look plausible while containing an identity swap or an implausible jump relative to neighboring frames.
Review complete action segments for temporal consistency. Pay particular attention when a hand reappears after occlusion.
Interpolation can help between suitable frames, but abrupt motion and contact events need closer inspection.
6. Validate the Export in the Training Pipeline
Before accepting a batch, load it through the intended data loader.
Check keypoint order, coordinate scaling, timestamps, identifiers, missing-value handling, and image transformations. Labels created on undistorted images must not be applied to distorted frames without the corresponding transformation.
Define Quality Metrics Before Production
Acceptance criteria should describe measurable properties rather than broad promises of “high accuracy.”
| Quality area | Suggested check | Important limitation |
|---|---|---|
| Structural validity | Required points, edges, and identifiers | Valid structure does not prove correct placement |
| 2D localization | Pixel error or normalized keypoint accuracy | Results depend on image scale and threshold |
| 3D localization | Mean per-joint position error | Coordinate frame and alignment must be stated |
| Temporal consistency | Unexpected jumps and identity changes | Real fast movement must remain distinguishable |
| Coverage | Required tasks and difficult conditions | Aggregate totals can hide missing scenarios |
Ego-Exo4D’s hand-pose benchmark reports both MPJPE and PA-MPJPE. The latter applies alignment before measuring joint error, so the two metrics answer different questions.
For project acceptance, specify the evaluation subset, units, visibility policy, and calculation method. Never compare scores whose definitions differ.
Add Object and Task Context to Hand Keypoints
Skeleton annotation captures configuration. It does not fully explain interaction.
A pinching hand shape might represent holding a screw, turning a dial, or grasping an empty space. Useful task interpretation requires additional evidence.
Depending on the objective, add:
-
Object identities and tracks.
-
Manipulated parts or interaction regions.
-
Action start and end times.
-
Natural-language instructions.
-
Task success and failure labels.
-
Contact labels where observable or otherwise supported.
Contact deserves particular care. Two image regions appearing to touch does not establish force, pressure, or stable physical contact.
Illustrative Workflow: Warehouse Picking
A warehouse dataset could record reaching into bins, separating similar packages, grasping items, and placing them into containers.
Hand keypoints describe movement. Object tracks identify the selected package. Temporal labels distinguish grasping from transporting. Outcome labels record whether the correct item reached the destination.
This is an illustrative dataset design, not a reported Virdyn customer result.
Combine Real and Simulated Data Without Hiding the Differences
Simulation can expand coverage by varying objects, viewpoints, layouts, and environmental conditions.
However, synthetic visual realism does not guarantee realistic interaction dynamics. Contact behavior, material properties, lighting, and sensor effects can still differ from physical recordings.
A practical workflow is to:
-
Use real recordings to identify important scenarios.
-
Generate controlled variations in simulation.
-
Track synthetic and real data separately.
-
Evaluate on held-out real-world recordings.
-
Investigate performance by condition, not only overall averages.
For world-model development, also define sequence length, state representation, and available action information. Skeleton labels are one possible supervision layer, not a complete world-model dataset by themselves.
How Virdyn Supports Training-Ready Data Production
Virdyn’s supplied service description combines egocentric collection, multimodal dataset development, data processing, annotation, and quality inspection.
Its proposed workflow spans requirements analysis, scene design, task planning, collection, cleaning, labeling, review, and delivery.
Depending on project scope, deliverables may include:
-
RGB recordings.
-
IMU measurements and synchronization metadata.
-
Camera-pose or spatial information.
-
Body-motion and hand-operation labels.
-
Standardized or custom datasets.
-
Supporting documentation and validation reports.
Listed delivery formats include MP4, AVI, CSV, JSON, and PLY. These formats serve different purposes: video containers carry recordings, structured files carry metadata or labels, and PLY can represent spatial geometry.
The important question is not simply which extensions are available, but whether the package matches the intended training pipeline.
Start With a Pilot Specification
Before requesting production volume, prepare representative clips, target tasks, desired labels, output requirements, and acceptance criteria.
Ask Virdyn to confirm capture configuration, calibration deliverables, annotation scope, data rights, retention controls, and review procedures.
A focused pilot provides a stronger basis for scaling than an unqualified promise of more footage.
Frequently Asked Questions
What is a skeleton annotation tool?
It is software for labeling named landmarks and their connections on images or video. Depending on the tool, individual points may also include visibility states or other attributes.
How many keypoints should a hand dataset include?
Twenty-one landmarks per hand is a common convention. Choose the final schema according to the model, application, and compatibility requirements rather than adopting a count without review.
Can 2D skeleton annotation provide 3D ground truth?
Not by itself. Reliable 3D labels require additional evidence or reconstruction methods, appropriate calibration, and validation. Estimated 3D outputs should be identified as estimates.
How should annotators handle hidden finger joints?
Follow a documented visibility policy. Mark hidden or unlocatable joints appropriately, and distinguish inferred positions from directly observed locations.
Are hand keypoints sufficient for robot training?
Usually not for the complete training objective. Depending on the system, teams may also need object context, instructions, action targets, calibration, or robot-specific demonstrations.
What should a dataset delivery include besides videos?
Include the annotation schema, labels, timestamps, relevant calibration files, provenance, usage rights, quality results, and a clear description of missing or invalid data.
References
1. iMerit — “Master Complex Labeling with the Skeleton Annotation Tool”. Source for skeleton templates, connected keypoints, point-level attributes, and the described Ango Hub labeling workflow.
2. Ego-Exo4D — Dataset Documentation. Source for multimodal, multiview activity data and complementary pose, segmentation, language, and procedural annotations.
3. Ego-Exo4D — EgoPose Annotation Documentation. Source for 2D and 3D annotation structures, camera metadata, annotation provenance, and the 21-keypoint-per-hand convention.
4. Ego-Exo4D — EgoHandPose Benchmark. Source for the hand-pose estimation task and the definitions and reporting units of MPJPE and PA-MPJPE.
5. Ego-Exo4D — Tutorial: Undistort Frames and Overlay Annotations. Source for the relationship between image undistortion and correct annotation overlays.
Hot Tags: Skeleton Annotation, AI Data Annotation Services, Egocentric Data Collection, AI Training Data, Robotics Training Data, Pose Estimation, Keypoint Annotation, Multimodal Datasets, Computer Vision Annotation, Custom Dataset Development
SHARE


