Powering Physical AI with Real-World Ego Datasets

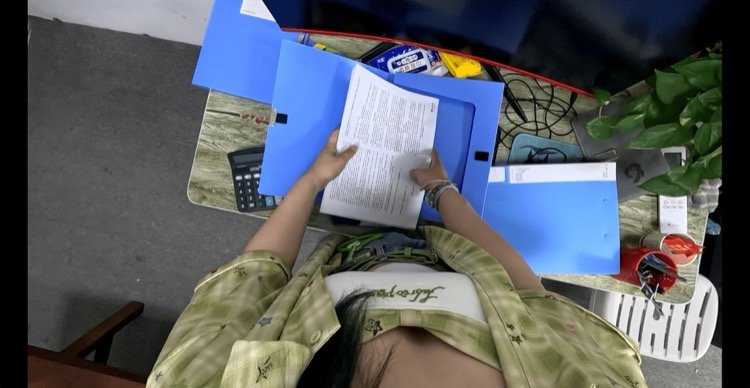
Pre-Labeling Automation for Embodied AI Training Data
Content Menu
● What Is Pre-Labeling Automation?
● Why Embodied AI Requires More Than Object Labels
>> First-Person Video Captures the Operator’s View
>> Human Demonstrations Are Not Robot Commands
● Design the Annotation Schema Before Recording
● A Practical Human-in-the-Loop Annotation Workflow
>> 1. Define Acceptance Criteria
>> 2. Capture and Inspect the Raw Data
>> 3. Establish a Human-Labeled Reference Set
>> 4. Generate Task-Specific Pre-Labels
>> 5. Review Sequences, Not Just Frames
>> 6. Audit and Release a Versioned Dataset
● Measure Whether Automation Actually Saves Work
● Control the Failure Modes That Matter in Egocentric Data
>> Occlusion and Identity Confusion
>> Automation Bias and Missing Labels
>> Synchronization and Coordinate Errors
>> Leakage Between Training and Evaluation
● Combine Real-World and Simulated Data Deliberately
● How Virdyn Connects Capture, Processing, and Delivery
● Specify Deliverables Beyond File Extensions
● Start With a Representative Pilot
>> Is Pre-Labeling Automation the Same as Automatic Annotation?
>> Can Egocentric Video Train a VLA Model by Itself?
>> What Should Humans Review First?
>> Does Higher Model Confidence Guarantee Correct Labels?
>> Can Simulation Replace Real-World Collection?
>> What Should a Dataset Pilot Deliver?
Pre-labeling automation helps AI teams turn raw recordings into useful training annotations without drawing every box, mask, or action boundary from scratch. For embodied AI, however, faster labeling is only part of the challenge. The dataset must also preserve what happened, when it happened, and how a person interacted with the physical environment.
Virdyn (VDEgo) brings this problem into focus through first-person data collection, multimodal dataset development, annotation, and collection hardware. The practical opportunity is to connect these capabilities into a controlled workflow: capture reliable observations, generate annotation drafts, validate difficult interactions, and deliver documented data that fits the intended training pipeline.
What Is Pre-Labeling Automation?
Pre-labeling automation uses models, rules, or specialized algorithms to propose initial annotations. Human reviewers then accept, edit, reject, or supplement those proposals.
For egocentric video, a draft might identify a tool, segment a hand, track a container, or suggest when a manipulation begins. These outputs are suggestions, not verified ground truth.
The distinction matters because a visually convincing annotation can still be operationally wrong. A mask may follow the correct object while missing the exact moment it is grasped. An action description may sound reasonable while confusing an attempted placement with a completed one.
My guiding principle for workflow design is simple: automate the draft, not the definition of correctness.
Why Embodied AI Requires More Than Object Labels
Embodied systems must connect perception with interaction. Recognizing a cup is different from understanding that someone grasped it, moved it behind an obstruction, and placed it upright.
First-Person Video Captures the Operator’s View
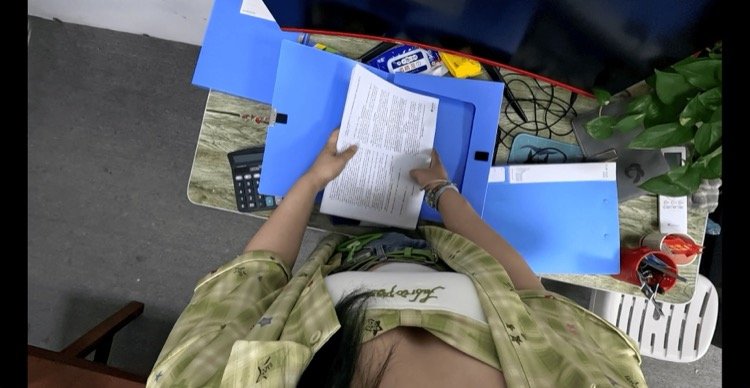
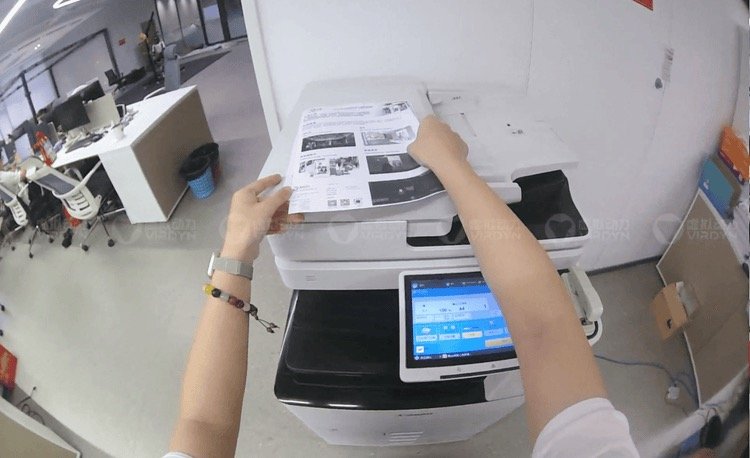
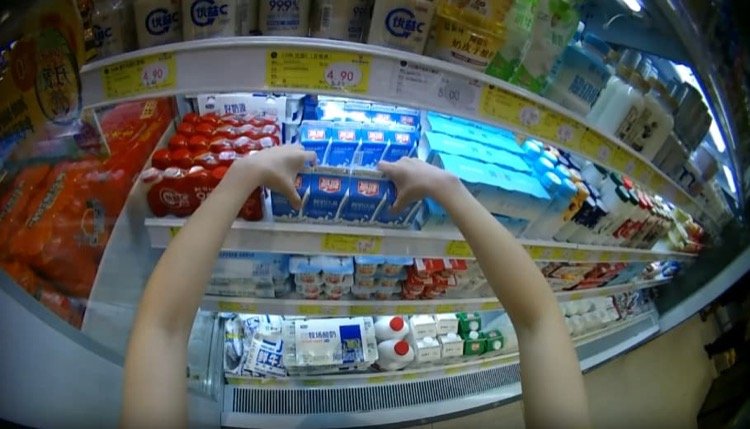
Egocentric footage records activity from the wearer’s perspective. It exposes hand–object interactions, changing viewpoints, and partial occlusions that a fixed camera may capture differently.
The initial Ego4D release contained 3,670 hours of video from 931 camera wearers across 74 locations. Its scale illustrates the breadth of first-person activity research, not a required dataset size for every project.
Human Demonstrations Are Not Robot Commands
Human video can support learning about objects, tasks, and interaction sequences. It does not automatically provide robot joint positions, actuator commands, or executable control trajectories.
This distinction becomes critical for Vision-Language-Action models. Teams must specify whether they need visual demonstrations, language descriptions, robot action data, or paired supervision. For world-model projects, the required prediction targets and temporal structure also need explicit definition.
DROID offers a useful contrast: its published dataset includes 76,000 robot demonstration trajectories, approximately 350 interaction hours, across 564 scenes and 86 tasks. Human observation data and robot demonstrations serve related but distinct purposes.
Design the Annotation Schema Before Recording
The most expensive annotation mistake often happens before labeling begins: collecting footage that cannot answer the intended training question.
Start with the target behavior. A warehouse project might need to distinguish picking, checking, placing, and recovering from a failed grasp. A household project may require opening a drawer, locating an object, and returning it to its original position.
Translate that behavior into a written annotation schema:
-
Object categories and persistent instance identifiers.
-
Hand visibility, interaction states, and occlusion rules.
-
Action names with explicit start and end conditions.
-
Success, failure, interruption, and recovery labels.
-
Language instructions and their relationship to demonstrated actions.
-
Sensor metadata, calibration references, and missing-data indicators.
Include examples of ambiguous cases. If an operator touches a package without moving it, reviewers should know whether that counts as contact, grasping, or neither.
A Practical Human-in-the-Loop Annotation Workflow
A reliable workflow connects collection quality with annotation decisions rather than treating them as separate services.
1. Define Acceptance Criteria
Agree on the unit of delivery: frames, clips, interactions, or complete episodes. Define required labels, review coverage, allowable uncertainty, and rejection conditions before production starts.
2. Capture and Inspect the Raw Data
Check visibility, exposure, motion blur, completeness, and sensor continuity. For stereo capture, confirm calibration records and usable overlap between views. Verify synchronization rather than assuming matching filenames imply aligned streams.
3. Establish a Human-Labeled Reference Set
Create a representative reference subset with adjudicated labels. Include difficult lighting, occlusion, repetitive objects, unsuccessful actions, and uncommon task variants. This set provides an independent basis for evaluating annotation drafts.
4. Generate Task-Specific Pre-Labels
Apply suitable detection, segmentation, tracking, or action-proposal tools. SAM 2, for example, supports promptable segmentation in images and videos. It can assist mask creation, but it does not independently establish task semantics or robot control targets.
5. Review Sequences, Not Just Frames
Reviewers should inspect the surrounding interaction. Check object identity before and after occlusion, handoffs between hands, and whether an apparent action actually succeeded.
6. Audit and Release a Versioned Dataset
Run schema validation, sample independent reviews, resolve disagreements, and package accepted outputs with their metadata. Keep rejected records and correction histories traceable rather than silently overwriting them.
Measure Whether Automation Actually Saves Work
Faster inference is not the same as faster accepted delivery. A weak draft can increase correction time, especially when reviewers must discover missing objects or undo persistent tracking mistakes.
Run a matched pilot comparing manual annotation with assisted annotation on comparable data. Use the same acceptance criteria and account for review, rework, and processing overhead.
| Metric | What it reveals |
|---|---|
| Human minutes per accepted episode | Whether drafting and correction reduce total labor |
| First-pass acceptance rate | How often outputs meet the agreed specification |
| Missed-object rate | Whether reviewers find objects absent from drafts |
| Identity switches per sequence | Whether tracking preserves object continuity |
| Action-boundary error | How closely temporal labels match adjudicated events |
| Cost per accepted episode | Whether savings survive infrastructure and rework costs |
A useful decision rule is to compare complete workflows, not model outputs in isolation. Retain manual labeling for categories where correction costs exceed the effort of starting fresh.
These metrics are proposed operating measures, not published Virdyn performance results. No universal speedup or accuracy percentage should replace a project-specific pilot.
Control the Failure Modes That Matter in Egocentric Data
Occlusion and Identity Confusion
Hands frequently hide the objects they manipulate. Similar containers may also cross paths. Require reviewers to verify identity across the sequence and mark uncertainty when the footage cannot support a confident decision.
Automation Bias and Missing Labels
A pre-label can anchor a reviewer’s attention to what the model found. Schedule blind audits on a sample of raw recordings so reviewers also search for omissions, not merely correct visible suggestions.
Synchronization and Coordinate Errors
A video label can appear accurate while being associated with the wrong sensor time. Document timestamp conventions, clock alignment, coordinate frames, and calibration versions. Set tolerances according to the task rather than claiming one timing threshold suits every application.
Leakage Between Training and Evaluation
Near-duplicate clips from the same session can make evaluation less informative. Define splits around the generalization question: unfamiliar operators, environments, objects, or task combinations. Preserve session identifiers so those boundaries can be checked.
Combine Real-World and Simulated Data Deliberately
Simulation can generate controlled variations and annotations that are difficult to obtain manually. However, rendered scenes may differ from real recordings in lighting, materials, contact behavior, camera motion, and sensor artifacts.
A practical strategy has three stages:
-
Establish a real-world reference set covering the intended operating conditions.
-
Use simulation to expand selected variations or investigate underrepresented scenarios.
-
Evaluate models on held-out real data before treating synthetic expansion as beneficial.
Keep data origin visible in the metadata. Synthetic labels may be exact relative to a simulator while still being imperfect representations of physical interactions.
For Virdyn projects, real capture and simulation should therefore be scoped as complementary inputs. Their proportions should follow validation results, not a fixed promise that more synthetic footage necessarily improves performance.
How Virdyn Connects Capture, Processing, and Delivery
Based on the supplied company brief, Virdyn offers requirements analysis, scenario design, task planning, first-person collection, cleaning, annotation, quality inspection, and delivery.
Its VDEgo-C2 stereo capture device is described as supporting dual RGB recording, synchronized IMU data, timestamps, camera pose tracking, local storage, and wireless remote control. Buyers should confirm exact specifications, calibration procedures, operating limits, and sample outputs for their configuration.
Depending on project scope, dataset development may include video, inertial measurements, pose information, spatial data, human movement, and hand interactions. Availability should be confirmed per project; these outputs are not interchangeable or necessarily measured directly by one device.
Virdyn describes both off-the-shelf and custom dataset options across industrial, warehouse, household, retail, and laboratory settings. The appropriate choice depends on task coverage, usage rights, sensor requirements, and annotation compatibility.
A practical engagement should establish those requirements before committing to collection volume.
Specify Deliverables Beyond File Extensions
MP4, AVI, CSV, JSON, and PLY are useful delivery formats, but a file extension alone does not make data training-ready.
A complete handover specification should cover:
-
Video resolution, frame rate, encoding, and stream identifiers.
-
Timestamp units, synchronization method, and missing-sample handling.
-
Camera calibration, pose conventions, and spatial coordinate frames.
-
Annotation schema, category definitions, and dataset version.
-
Episode boundaries, task outcomes, and split assignments.
-
Consent, licensing, permitted uses, access rules, and retention terms.
Request a sample package and test ingestion before approving the full delivery. This exposes integration problems while changes remain inexpensive.
Start With a Representative Pilot
Share your target tasks, operating environments, sensor requirements, annotation schema, and intended training pipeline with Virdyn. Request a scoped pilot containing representative interactions and difficult cases, together with proposed review and acceptance procedures.
Evaluate capture usability, correction effort, temporal consistency, and delivery compatibility before scaling. The objective is not the largest collection of recordings. It is a dataset whose contents, limitations, and permitted uses are clear enough for your team to train and evaluate responsibly.
Frequently Asked Questions
Is Pre-Labeling Automation the Same as Automatic Annotation?
Not necessarily. Pre-labeling produces drafts intended for review. Fully automatic annotation may omit that review stage. Specify the actual validation process rather than relying on the service name.
Can Egocentric Video Train a VLA Model by Itself?
It can contribute visual and behavioral information, but raw video does not automatically include executable robot actions. The required supervision depends on the model architecture and training objective.
What Should Humans Review First?
Prioritize ambiguous interactions, occlusions, rare categories, failed actions, and unfamiliar environments. Also audit a representative sample of apparently straightforward outputs so systematic omissions do not remain hidden.
Does Higher Model Confidence Guarantee Correct Labels?
No. Treat confidence as a routing signal, not proof. Assess it against adjudicated examples from the intended domain and retain independent checks for missing or confidently incorrect predictions.
Can Simulation Replace Real-World Collection?
Not as a general assumption. Simulation can expand controlled coverage, but its value should be tested against held-out real recordings and the downstream behavior the dataset is intended to support.
What Should a Dataset Pilot Deliver?
Request sample raw recordings, reviewed annotations, calibration and synchronization documentation, a schema, a quality report, and an importable sample package. Agree in advance on how pilot acceptance will be decided.
References
1. iMerit. “Pre-Labeling Automation: Accelerating AI Annotation with Smarter First Drafts.” Background source for pre-labeling definitions, human review, temporal consistency, annotation bias, and quality-control challenges. https://imerit.ai/resources/blog/pre-labeling-automation-accelerating-ai-annotation-with-smarter-first-drafts/
2. Grauman, K., et al. “Ego4D: Around the World in 3,000 Hours of Egocentric Video.” CVPR, 2022. Source for the initial dataset’s 3,670 hours, 931 camera wearers, 74 locations, and first-person research context. https://arxiv.org/html/2110.07058v3
3. Khazatsky, A., et al. “DROID: A Large-Scale In-The-Wild Robot Manipulation Dataset.” 2024. Source for the 76,000 demonstration trajectories, approximately 350 interaction hours, 564 scenes, and 86 tasks. https://arxiv.org/html/2403.12945v1
4. Hugging Face Transformers Documentation. “SAM2 Video,” documenting Ravi, N., et al., “SAM 2: Segment Anything in Images and Videos.” Source for promptable image and video segmentation capabilities. https://huggingface.co/docs/transformers/en/model_doc/sam2_video
Hot Tags: AI Data Annotation Services, AI Training Data Services, Egocentric Data Collection, Embodied AI Datasets, Robotics Training Data, Multimodal Data Collection, Automated Data Labeling, Custom AI Datasets, Synthetic Data Generation, Computer Vision Annotation
SHARE



